CoreWeave Announces Vera Rubin Access and Forge AI Workflows
A September 30, 2026 NVIDIA report details CoreWeave Vera Rubin availability and Forge, linking model development with production feedback.
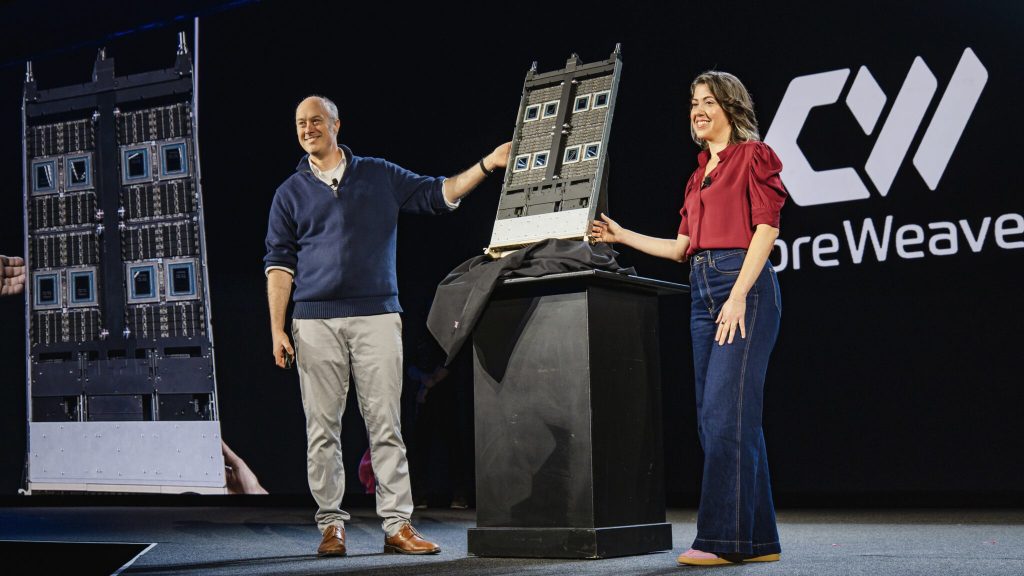
The September 30, 2026 announcement
NVIDIA reported that CoreWeave announced Vera Rubin NVL72 availability at its Fully Connected event, with Cognition identified as the first customer running production workloads on the platform. The announcement also covered CoreWeave Forge, a connected environment for training, evaluating, and improving models and agents. NVIDIA's dated report is the primary source for these launch details.
What the platform changes are intended to connect
The report describes Forge as bringing experiment tracking, post-training work, and production signals into a related workflow. It also distinguishes generally available services from preview capabilities and says CoreWeave plans to offer the Vera CPU. Those stages matter: an announced future offering, a private preview, and a generally available service should not be treated as equivalent access.
Editorial analysis: close the evidence loop before the training loop
A production system produces many observations, but an observation is not automatically a useful training example. Teams first need to understand what happened, what the desired behavior was, and whether the example is representative. A connected platform can help organize that work, but the organization still needs a process for deciding which signals are trustworthy and which changes are worth trying.
Start with a failure taxonomy. Separate incorrect facts, poor retrieval, unsuccessful tool calls, misunderstood instructions, and application errors. A model change may help one category and do little for another. If a document was never available to the assistant, more elaborate reasoning cannot recover its contents. If the application passes an incorrect parameter, the relevant fix may be outside the model entirely.
Next, preserve an evaluation set that is distinct from the examples used to improve the system. Otherwise a new version can appear stronger because it has been optimized for the cases being counted. Include both common tasks and less frequent failures that have meaningful consequences. Record the model, prompt, tools, and application configuration for each run so that results remain interpretable after the system changes.
Infrastructure selection should follow those requirements. A research team running experiments, a service handling interactive requests, and an agent executing many tool calls place different demands on compute and orchestration. List the actual workload and its constraints before using a platform demonstration as a purchasing argument. Availability of a new system is useful news, but the relevant decision is whether it improves the team's accepted outputs under its own conditions.
Limits and availability context
The report includes customer and vendor performance statements. They are not independent measurements by this publication and should not be generalized to every workload. Readers should verify the current service catalog, capacity options, preview terms, and region support directly. This article does not provide a price quote, a guaranteed allocation, or a claim about a customer's likely return on investment.
What readers should verify
For a platform evaluation, ask for an end-to-end example using a representative task. Follow it from input through model inference, tool execution, logging, evaluation, and any proposed improvement. Check whether the system makes it possible to explain why a particular result was judged incorrect. A dashboard is useful only when its measures lead to an understandable engineering decision.
Consider data handling as part of the workflow design. Decide which traces should be kept, who may review them, and how sensitive content is excluded from reusable examples. Those choices should be explicit before production observations become a development dataset. Also define how a change is rolled back if an improvement in one test creates a regression elsewhere.
The most informative follow-up evidence will be repeatable improvements on clearly described tasks, with the evaluation conditions preserved. Teams can use the announcement to explore a more connected toolchain while keeping responsibility for the quality of their own evidence.
Factual FAQ
Is every mentioned capability generally available?
No. The source uses different availability stages for different services.
Does a vendor benchmark predict every deployment?
No. A comparison needs matching workload, configuration, and measurement conditions.
Additional primary-source context
CoreWeave’s own launch announcement confirms Forge’s September 30 introduction and describes a cycle of running, observing, curating, improving, and evaluating. Its accompanying product explanation discusses portable improvement data and working across models, frameworks, and infrastructure. Those are vendor descriptions of the intended workflow. A team assessing portability should request a practical export and integration demonstration with its own evaluation artifacts.
Supporting documentation: CoreWeave: Forge launch announcement; CoreWeave: Forge workflow explanation.
Sources and reporting note
NVIDIA: official announcement (2026-09-30). Reporting checked on October 16, 2026. This article separates the announced facts from our editorial analysis; it is not a hands-on product test. Feature access and program terms can change after publication.