Avian
Avian runs open LLMs such as DeepSeek, GLM, Kimi, MiniMax and MiMo behind an OpenAI-compatible API billed per token from prepaid credits. It also rents dedicated NVIDIA B200 and B300 nodes. Built for developers and AI teams.
What is Avian?
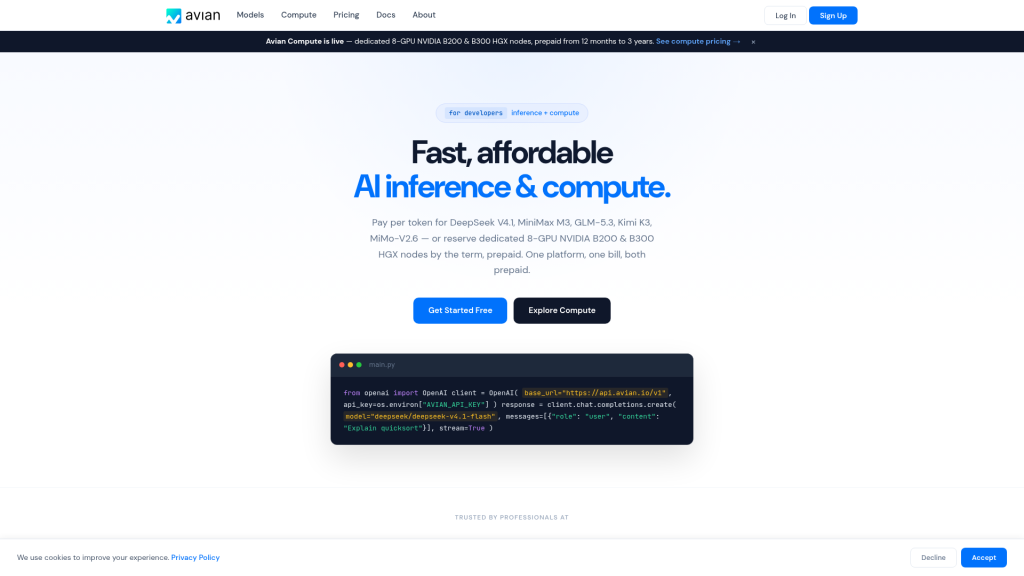
Avian is an AI inference provider. It hosts popular open large language models and exposes them through an API that follows the OpenAI Chat Completions format, so existing code built on the OpenAI SDK can switch to Avian by changing the base URL and key. Usage is billed per token from a prepaid balance, with no subscription.
Avian also sells reserved GPU compute: whole 8-GPU NVIDIA B200 and B300 nodes rented for fixed terms. The service is aimed at developers, startups and engineering teams who want fast, low-cost access to open models, including people who plug those models into AI coding tools. Sign-up is on the official Avian website.
Key Features of Avian
OpenAI-Compatible Endpoint
The API mirrors the familiar chat-completions format, including streaming, so migrating an app usually needs only a configuration change rather than a rewrite.
Open Model Catalogue
Ten models are listed across the DeepSeek, Kimi, GLM, MiniMax and MiMo families, with context windows up to one million tokens on most of them. Every model is available to every account.
Speed-Focused Hosting
Models run on NVIDIA B200 GPUs with speculative decoding. Avian publishes its own throughput figures; treat them as vendor benchmarks and test with your own prompts.
Coding Tool Support
Avian says it works with more than 20 coding tools, including Cursor, Claude Code, Cline, Windsurf and Kilo Code, as a cheaper model backend.
Privacy and Compliance
The company states that request data is not retained and that infrastructure runs on SOC 2 approved Microsoft Azure, with GDPR and CCPA compliance.
Dedicated GPU Nodes
For large workloads you can reserve single-tenant B200 or B300 HGX nodes, prepaid for the whole term, with rates locked at order.
Avian Pricing
Inference is pay as you go: you top up credits (the site offers $50, $100, $150 and $250 options) and each request deducts its token cost. Credits do not expire and there are no rate limits. Selected per-million-token prices:
Reserved B200 GPUs are listed from $4.32 per GPU-hour on a 12-month term down to $3.42 on a 3-year term ($719,021 per node prepaid); B300 runs from $4.95 to $4.23. Terms shorter than 12 months were shown as sold out, and compute is available in the US only.
Prices checked on October 27, 2026; check the official pricing page for current plans.
Who Should Use Avian?
- Developers who want cheap, fast open models behind an OpenAI-style API
- Teams using AI coding assistants that accept a custom model endpoint
- Startups building features on long-context models
- Organisations needing dedicated, single-tenant GPU capacity
Is Avian Worth It?
If open models are good enough for your task, Avian is an easy, low-cost way to use them. The OpenAI-compatible API, non-expiring credits and lack of rate limits remove most friction, and the privacy statements are reassuring for production use.
Keep its limits in view. You will not find proprietary models such as GPT, Claude or Gemini here, the headline speed and cost comparisons are the vendor's own and use older rival models, and the dedicated GPU offer is only practical for well-funded teams. Load a small credit balance, benchmark your real workload, and compare with other inference providers before scaling up.